
This article explains how to use the AMD Radeon™ GPU Analyzer (RGA) to correlate the AMD GPU ISA disassembly of a pre-compiled Code Object back to the source code line that produced it. Basic RGA usage knowledge is assumed.
Introduction
Source to ISA correlation is not new to AMD RGA. OpenCL™ mode has supported it for a while. In OpenCL mode, RGA compiles the .cl kernel itself, so it knows which source line produced each of the AMD GPU ISA instructions.
If you loaded a pre-compiled Code Object built via a custom compilation path into RGA, you got the AMD GPU ISA disassembly and the resource usage statistics, but the correlation back to the source code was missing.
What’s new in AMD RGA 2.15?
Starting with the AMD RGA 2.15 release, Binary Analysis mode brings the same AMD GPU ISA to source code correlation for pre-compiled Code Objects. Drop in any AMD GPU Code Object that carries debug information and RGA extracts the mapping for you. Correlation is enabled by default in Binary Analysis mode, and RGA detects the debug information section when it loads the binary.
This is designed to work regardless of which toolchain produced the Code Object; it works from whatever debug information is embedded in the binary. The examples below use HIP, but Code Objects built from OpenCL C kernels correlate in exactly the same way.
Prerequisites
- AMD RGA 2.15 or later. Source to ISA correlation for pre-compiled binaries is new in this release.
- The Code Object needs to be compiled with debug information. For HIP, that is
-g. - The source files are reachable from the machine running RGA. The paths recorded in the debug information are the paths on the system that built the Code Object. If you are analyzing the binary on the machine that built it, this is automatic. If not, see Locating source files below.
Compiling with debug information
A prerequisite for using this feature is ensuring that the AMD GPU code object is compiled with debug information enabled.
Let’s build an AMD HIP Code Object for AMD CDNA™ 5 architecture (gfx1250 – AMD Instinct™ MI400 Series) GPUs with debug information using the AMD ROCm™ 10.0 toolchain:
amdclang++ -x hip --offload-arch=gfx1250 --offload-device-only --no-gpu-bundle-output \
-std=c++17 -O3 -g gemm.hip -o gemm.co
Here, the --offload-device-only option drops the host compilation, and the --no-gpu-bundle-output option writes the linked Code Object that can be loaded with RGA. -g records the DWARF debug information the correlation relies on.
Locating source files
The source file paths embedded in the debug information are point to paths on the same system that was used to build the Code Object. A binary produced on a build server or handed over by a colleague will likely refer to directories that do not exist on your machine.
If AMD RGA cannot find those files, it will prompt you for additional directories to search when the binary is loaded.
These directories can also be set in advance using the Additional source search paths setting in the Binary Analysis build settings.
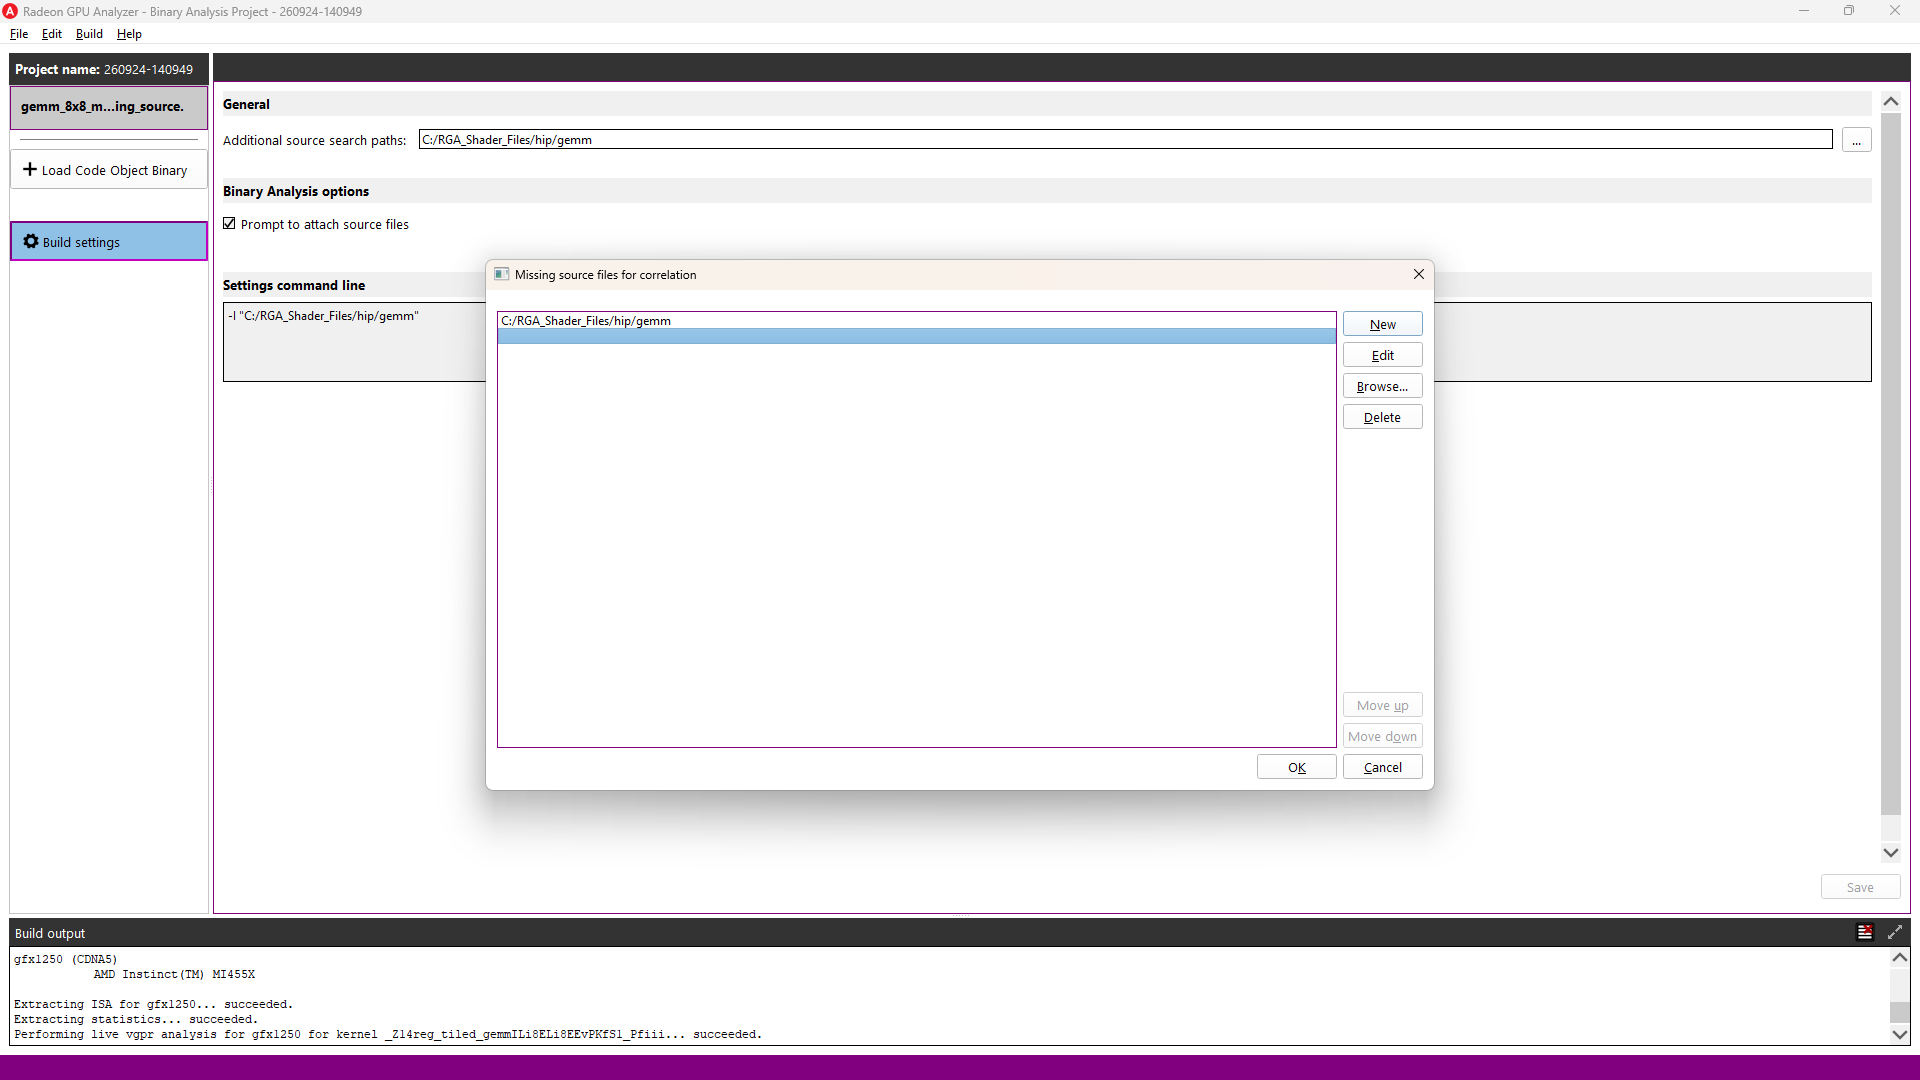
If the Code Object does not contain debug information, no error is reported. The disassembly is produced as usual and no Source Code View is shown.
Seeing it in the AMD RGA GUI
Load gemm.co into Binary Analysis mode in the AMD RGA GUI application. RGA identifies the target as gfx1250 (CDNA™ 5) and lists the kernel. Selecting it shows the AMD GPU ISA disassembly, with the Source Code View displayed alongside it, correlated in both directions.
Selecting a line in the Source Code View highlights every ISA instruction generated from it. Selecting an instruction in the Disassembly View highlights the source line that produced it.
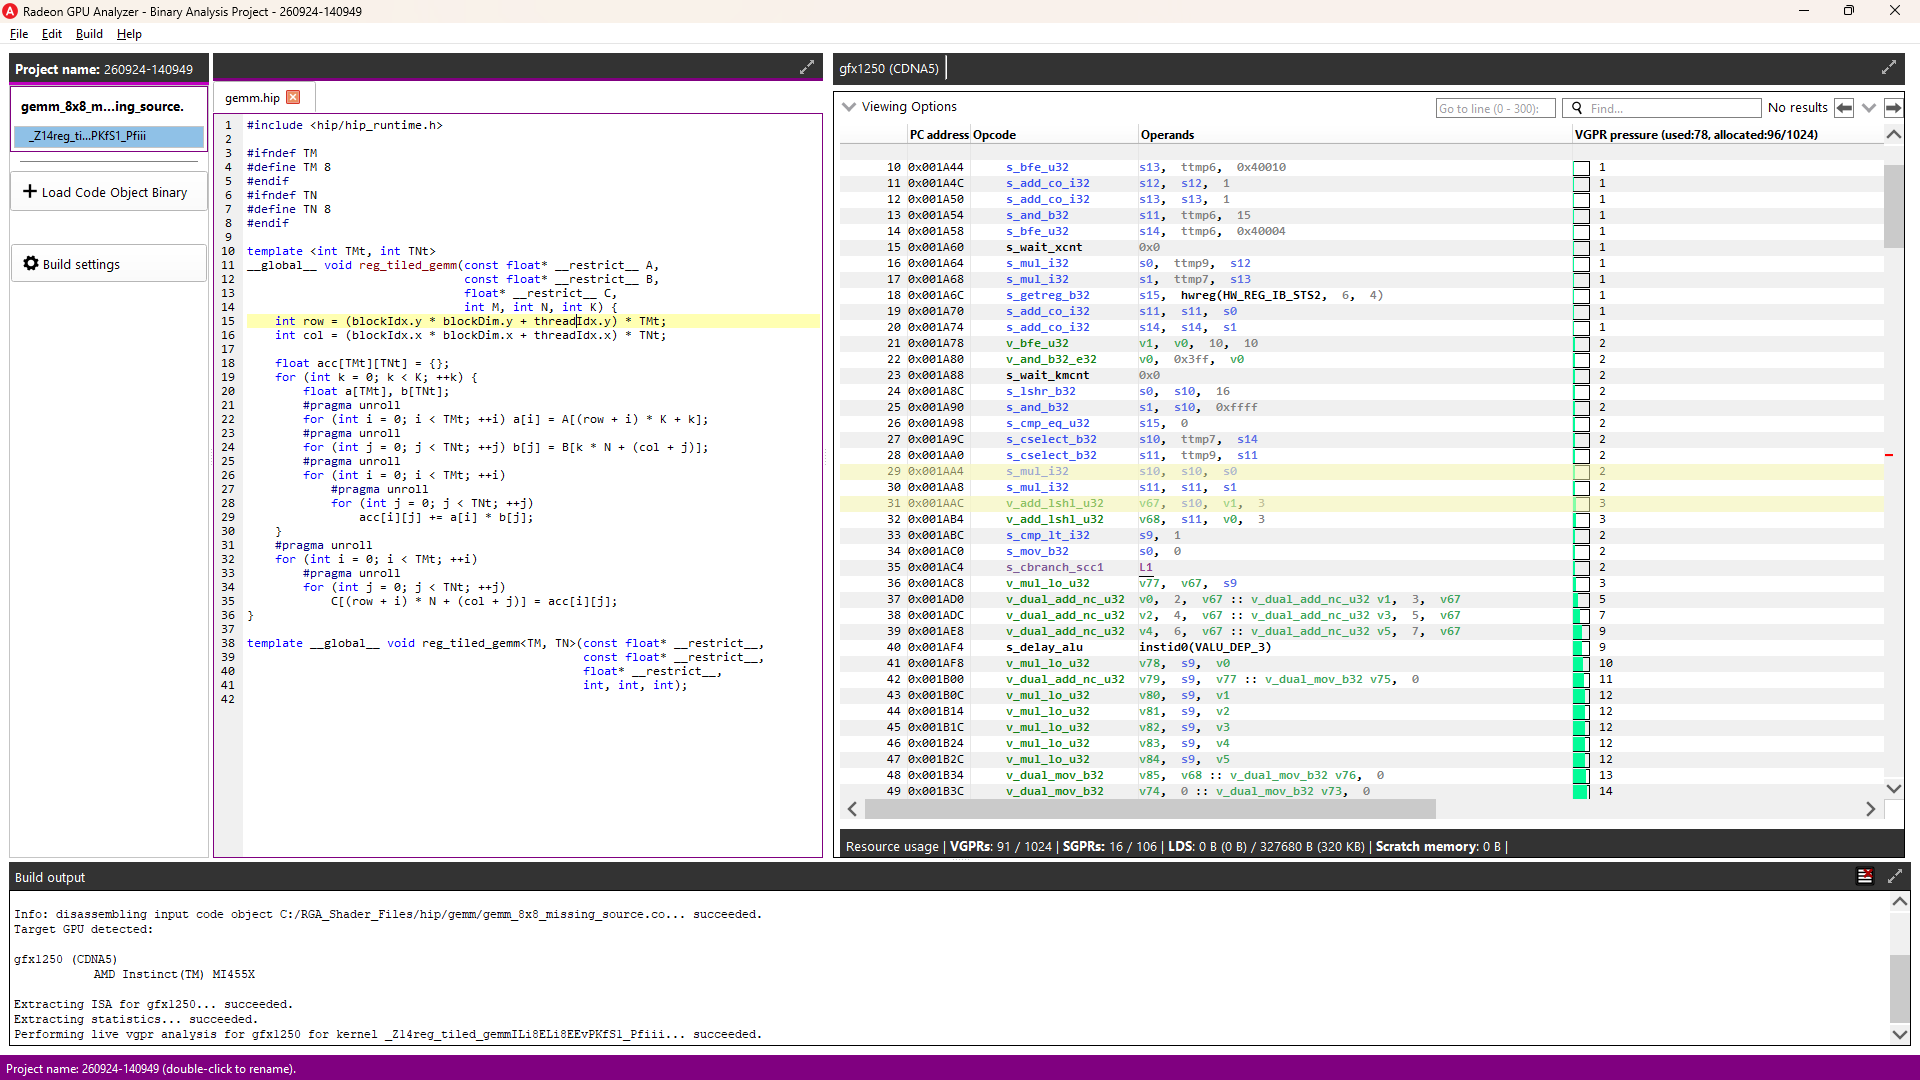
As a worked example, we will use a register-tiled SGEMM microkernel. Each thread computes a TMt × TNt tile of the output matrix and holds the accumulators in registers across the K-loop. Here is gemm.hip in full, built with TM = TN = 8:
1 #include <hip/hip_runtime.h>
10 template <int TMt, int TNt>
11 __global__ void reg_tiled_gemm(const float* __restrict__ A,
12 const float* __restrict__ B,
13 float* __restrict__ C,
14 int M, int N, int K) {
15 int row = (blockIdx.y * blockDim.y + threadIdx.y) * TMt;
16 int col = (blockIdx.x * blockDim.x + threadIdx.x) * TNt;
18 float acc[TMt][TNt] = {};
19 for (int k = 0; k < K; ++k) {
22 for (int i = 0; i < TMt; ++i) a[i] = A[(row + i) * K + k];
24 for (int j = 0; j < TNt; ++j) b[j] = B[k * N + (col + j)];
26 for (int i = 0; i < TMt; ++i)
28 for (int j = 0; j < TNt; ++j)
29 acc[i][j] += a[i] * b[j];
32 for (int i = 0; i < TMt; ++i)
34 for (int j = 0; j < TNt; ++j)
35 C[(row + i) * N + (col + j)] = acc[i][j];
38 template __global__ void reg_tiled_gemm<TM, TN>(const float* __restrict__,
39 const float* __restrict__,
Selecting each line in turn gives the number of instructions generated from it:
Line 29 contains 64 logical fused multiply-adds but maps to 40 instructions. The opcodes highlighted for it are 16 v_pk_fma_f32, 16 v_dual_fmac_f32, and 8 s_wait_loadcnt. The packed and dual-issue forms each perform two FMAs, so the 64 operations are carried by 32 instructions.
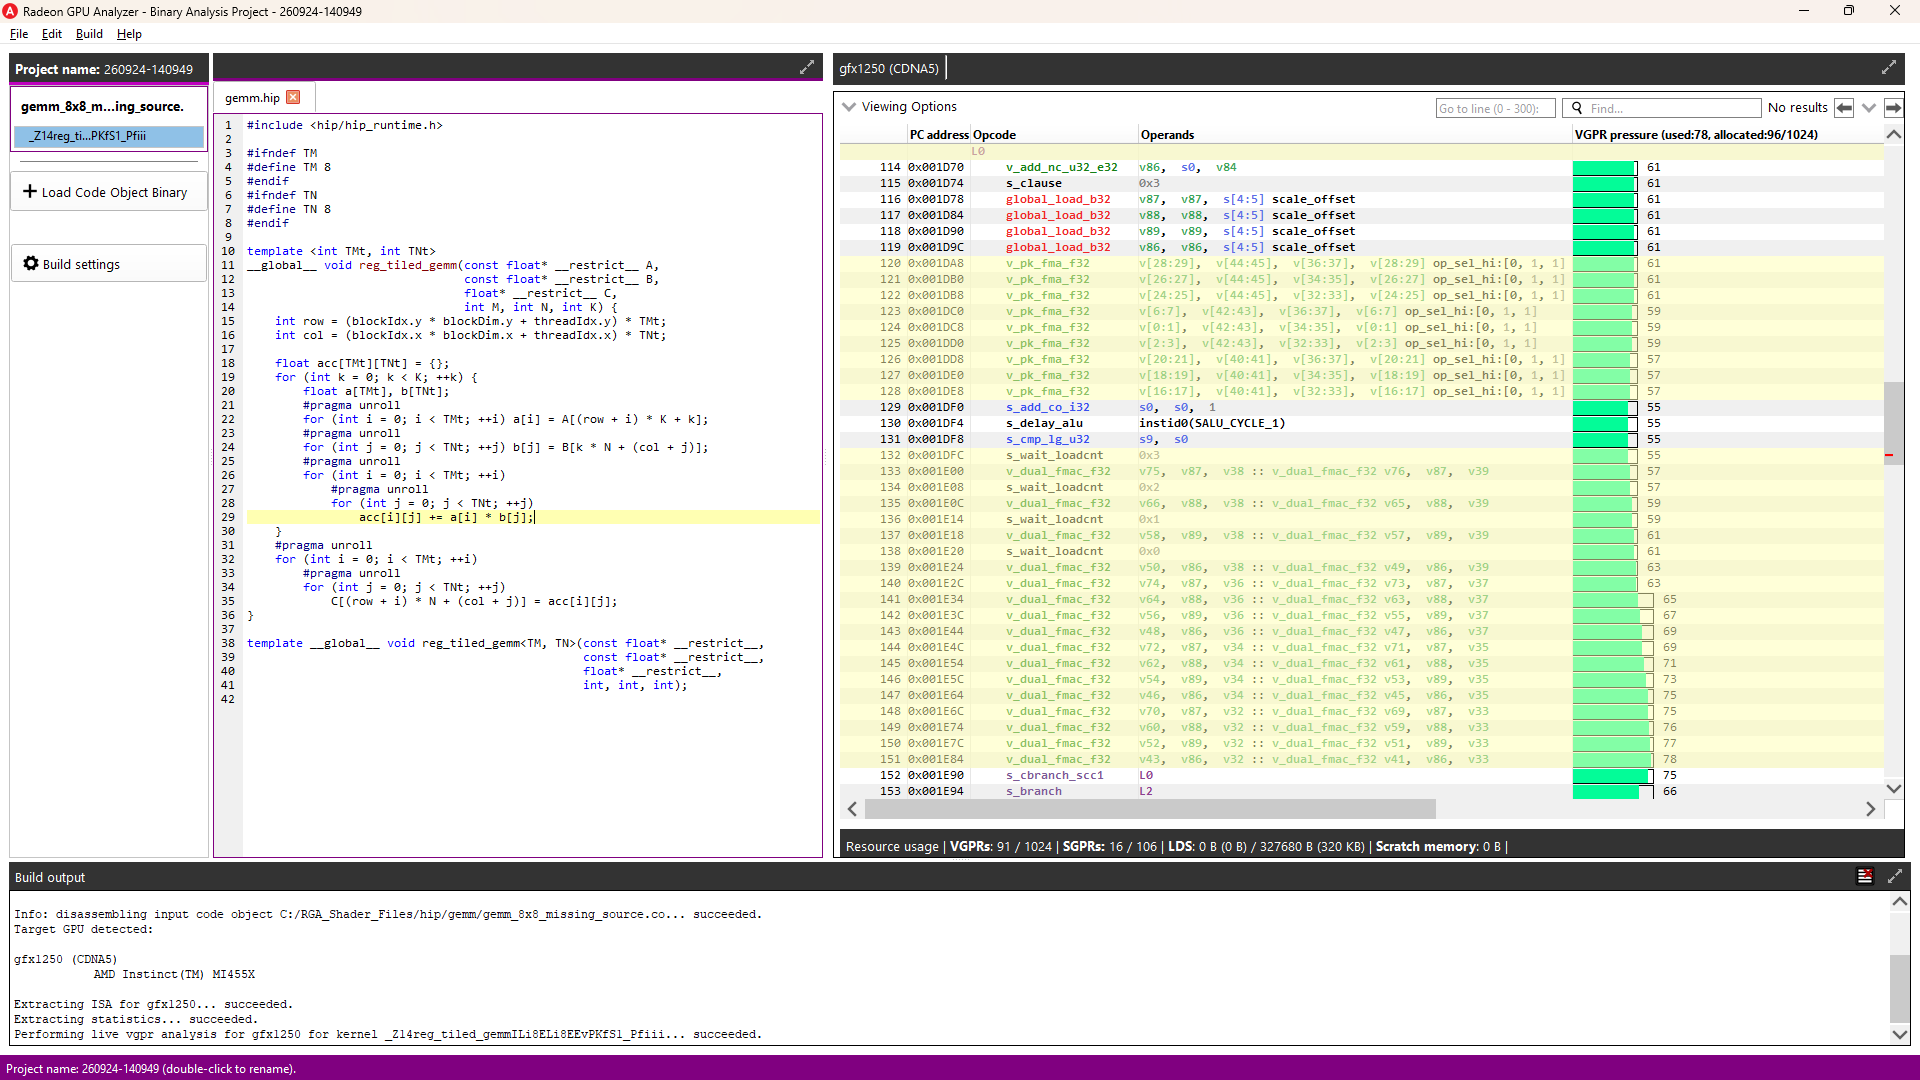
Line 35 is a single subscripted assignment that maps to 97 instructions. It consists of 32 global_store_b32, 8 global_store_b64, and address arithmetic.
Effect of tile size
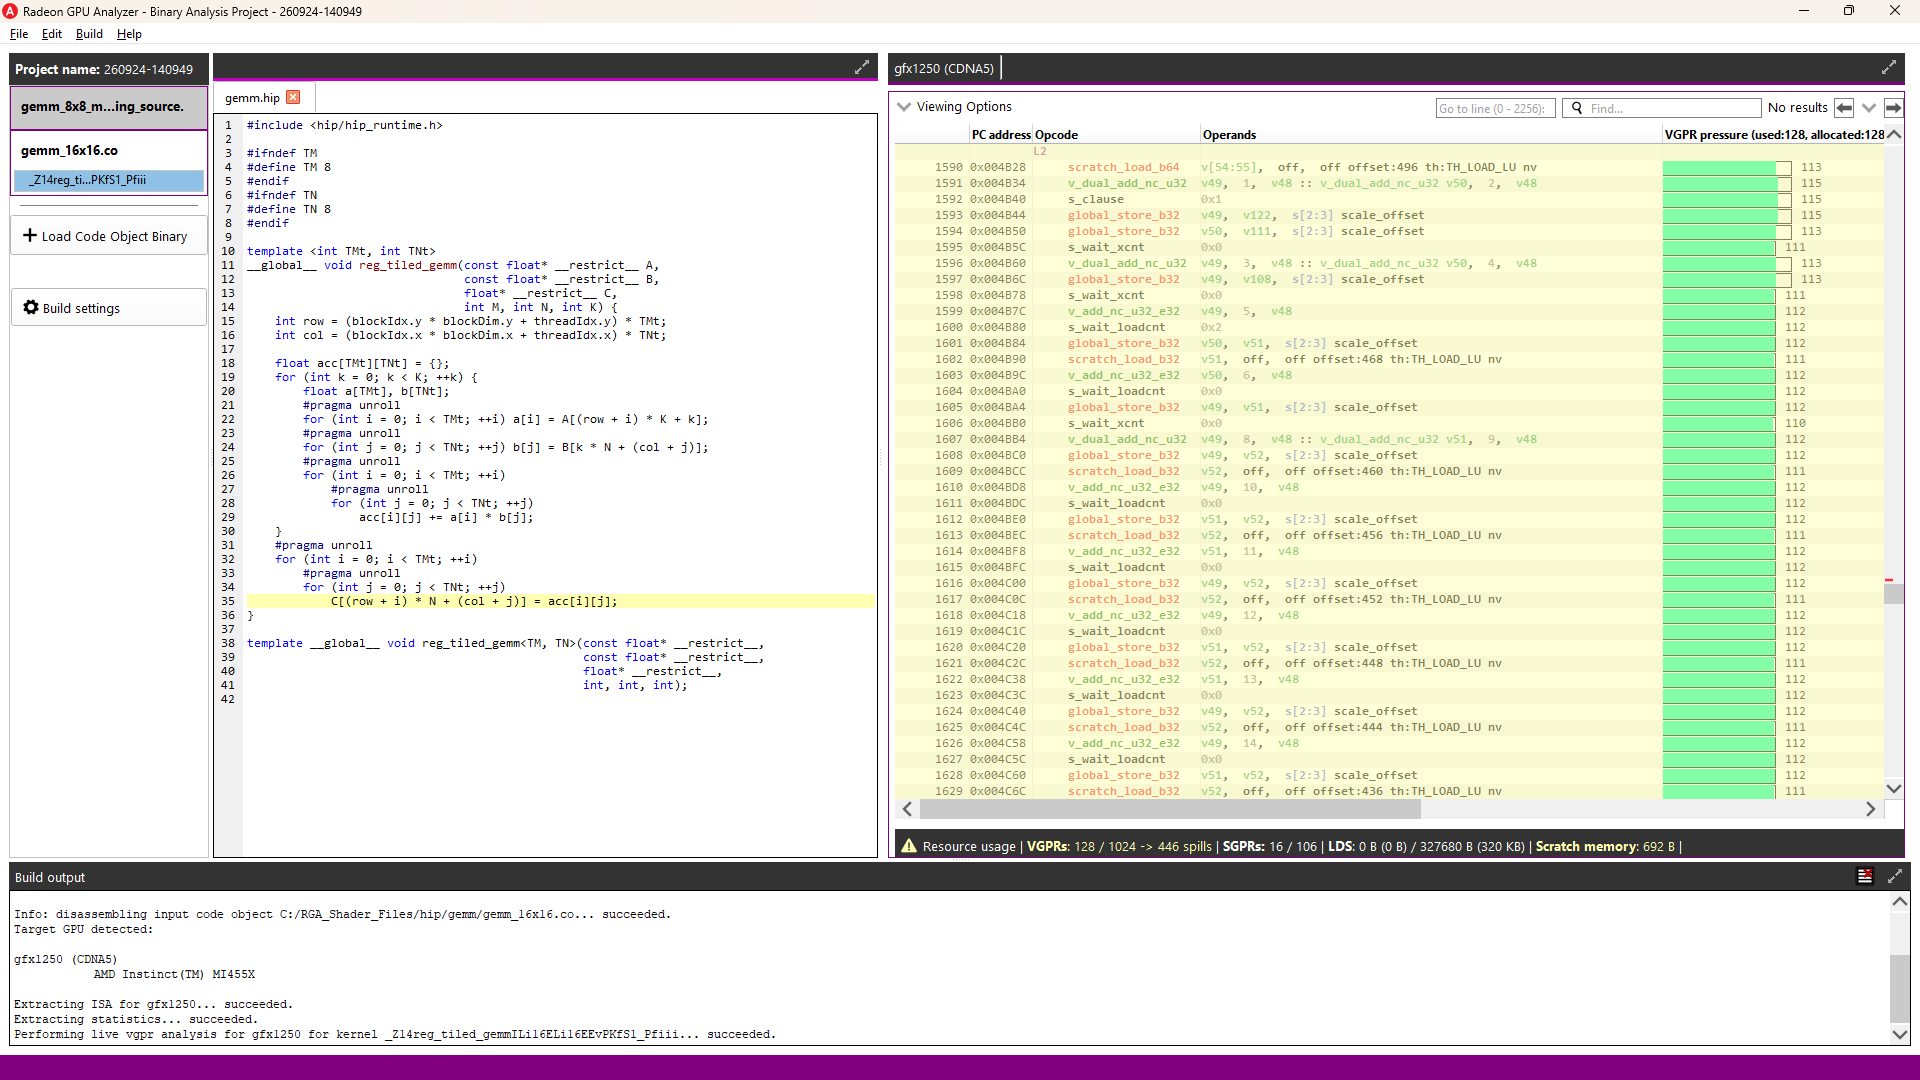
The tile size controls how many values the kernel holds live across the K-loop. Rebuilding with a 16 × 16 tile instead of 8 × 8 grows the ISA from 2,072 bytes to 13,968 bytes and introduces 671 scratch_* instructions, where the 8 × 8 build had none. Those are spill instructions: the tile no longer fits in the register file, so intermediate values are written out and reloaded.
Correlating those 671 instructions back to source gives:
Conclusion
Binary Analysis mode in AMD Radeon GPU Analyzer (RGA) 2.15 brings the same source-to-ISA correlation capabilities already available in OpenCL mode to any precompiled AMD GPU Code Object that contains debug information, regardless of the graphics or compute API from which it originated.
Resources
Disclaimers and attributions
OpenCL and the OpenCL logo are trademarks of Apple Inc. used by permission by Khronos.